AI/ML · Full Stack
SourceAtlas
Agentic RAG with verified citations
- Status
- Complete
- Year
- 2026
- Live application
- Runs locally with Docker Compose and Ollama. Single-tenant, not publicly deployed.
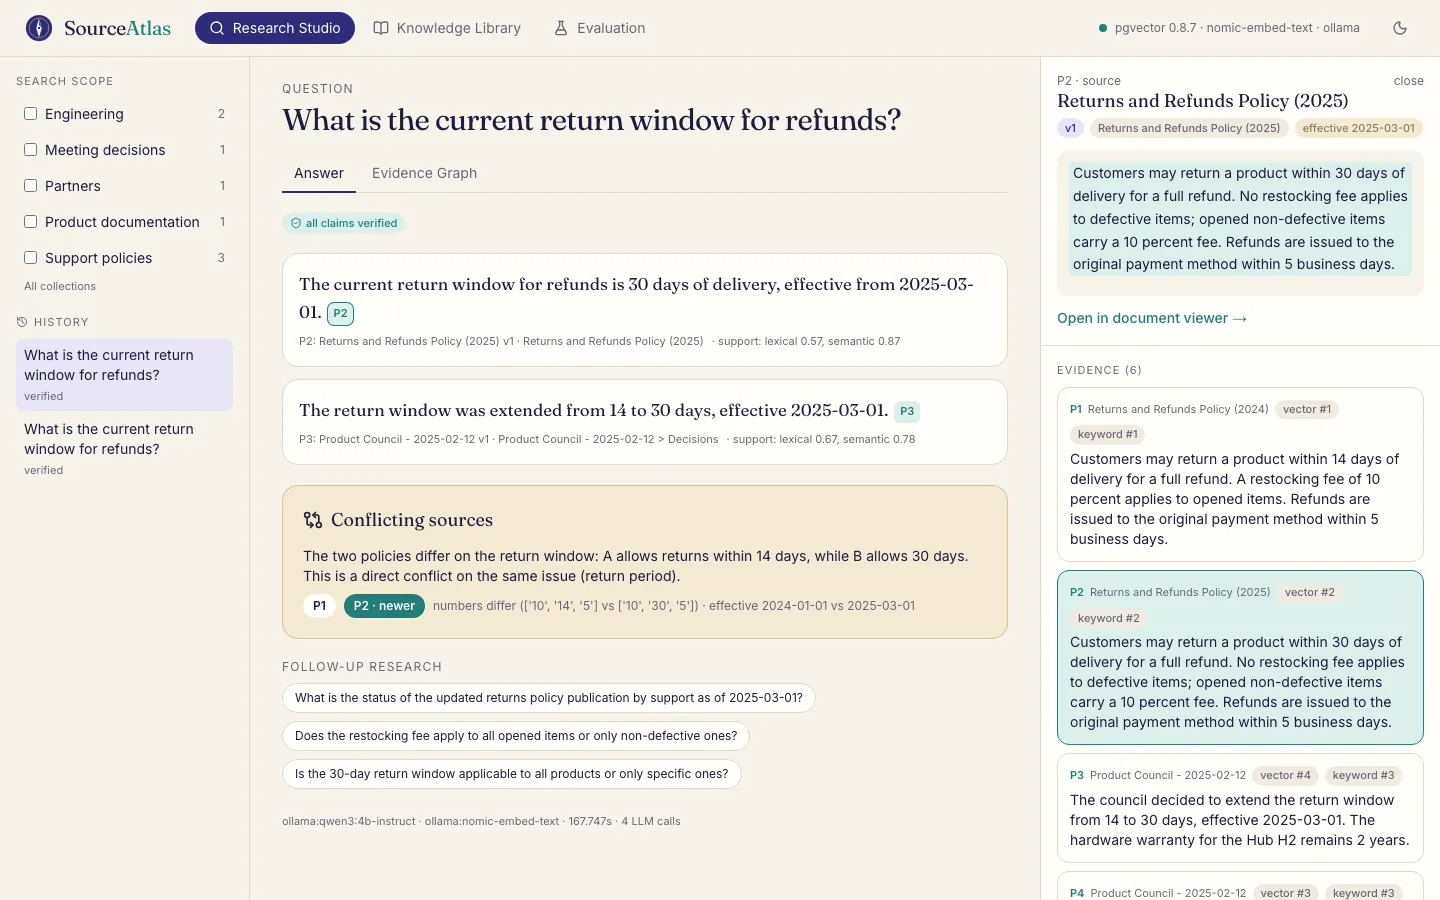
- answer correctness, live eval (16 questions)
- 92.3%
- answer correctness, live eval (16 questions)
- citation correctness, live eval
- 95.8%
- citation correctness, live eval
- Recall@5
- 1.00
- Recall@5
01 Problem
"Chat with your docs" tools produce fluent prose whose citations often don't support it. SourceAtlas treats an answer as a list of claims, verifies each claim against its cited passage, keeps page, section and version provenance, and refuses to answer when the evidence isn't there.
02 Product overview
A bounded LangGraph pipeline understands the question, runs hybrid retrieval, checks whether the evidence is sufficient, reformulates up to three times, reranks, detects conflicts, drafts, verifies each claim and either answers or abstains. Retrieved passages are screened for prompt injection, and web ingestion is SSRF-safe.
Implemented
- Hybrid search: pgvector HNSW + Postgres full-text (GIN), fused with reciprocal rank fusion (k=60)
- Claim-level verification against cited passages
- Conflict detection across documents and versions
- Prompt-injection quarantine for retrieved text and SSRF-safe web ingestion
- Ingestion of PDF, DOCX, HTML and TXT with document versions
- Evidence graph (React Flow), pdf.js viewer with cited-passage highlighting and an evaluation dashboard
Planned, not yet built
- Cross-encoder reranking
- NLI-based claim checking
- OCR
- Queue-based ingestion
- Per-user access control
03 System architecture
04 Core technologies
Retrieval & agents
- LangGraph
- PostgreSQL 16 + pgvector
- Ollama (qwen3:4b-instruct)
- nomic-embed-text
Backend
- Python 3.13
- FastAPI
- Pydantic 2
- SQLAlchemy 2
- Alembic
- PyMuPDF
- httpx
Frontend
- Next.js 16
- React 19
- Tailwind 4
- React Flow
- pdf.js
- Plotly
Quality
- ruff
- mypy --strict
- pytest
- Vitest
- Playwright
- pip-audit
- gitleaks
05 Engineering challenges
From 190 seconds to 13
An unbounded agent loop was too slow. Bounding the graph cut median latency from about 190 s to about 13 s.
Verifying without another LLM
Claims are checked deterministically against their passages rather than by an LLM judge, so verification is reproducible.
Hostile passages
Injected instructions inside documents are sanitised and quarantined rather than silently dropped, keeping provenance intact.
06 Technical decisions
- 01One Postgres for metadata, vectors and full-text search
- 02Reciprocal rank fusion rather than tuned score weights
- 03Answers as lists of claims, not paragraphs
- 04The model's collection guess is a hint, not a filter
07 Verified test results
- pytest
- 76 passed
- Playwright E2E
- 7/7
- Vitest
- 2/2
Latest GitHub Actions run on main: passing. Counts as reported in the repository's README and testing docs.
Explore the results interactively in the Lab08 Screenshots
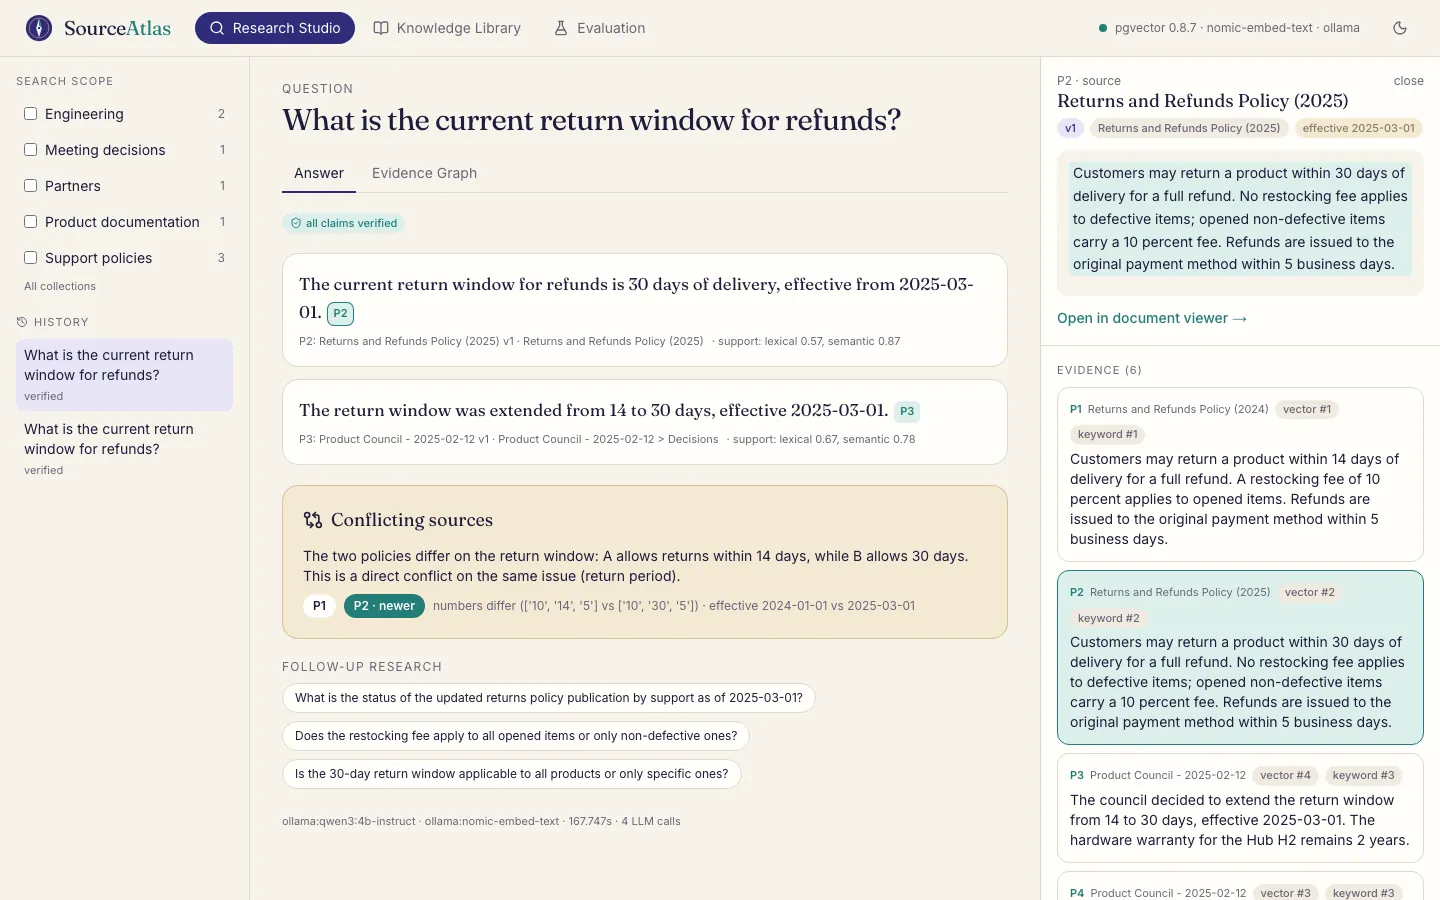
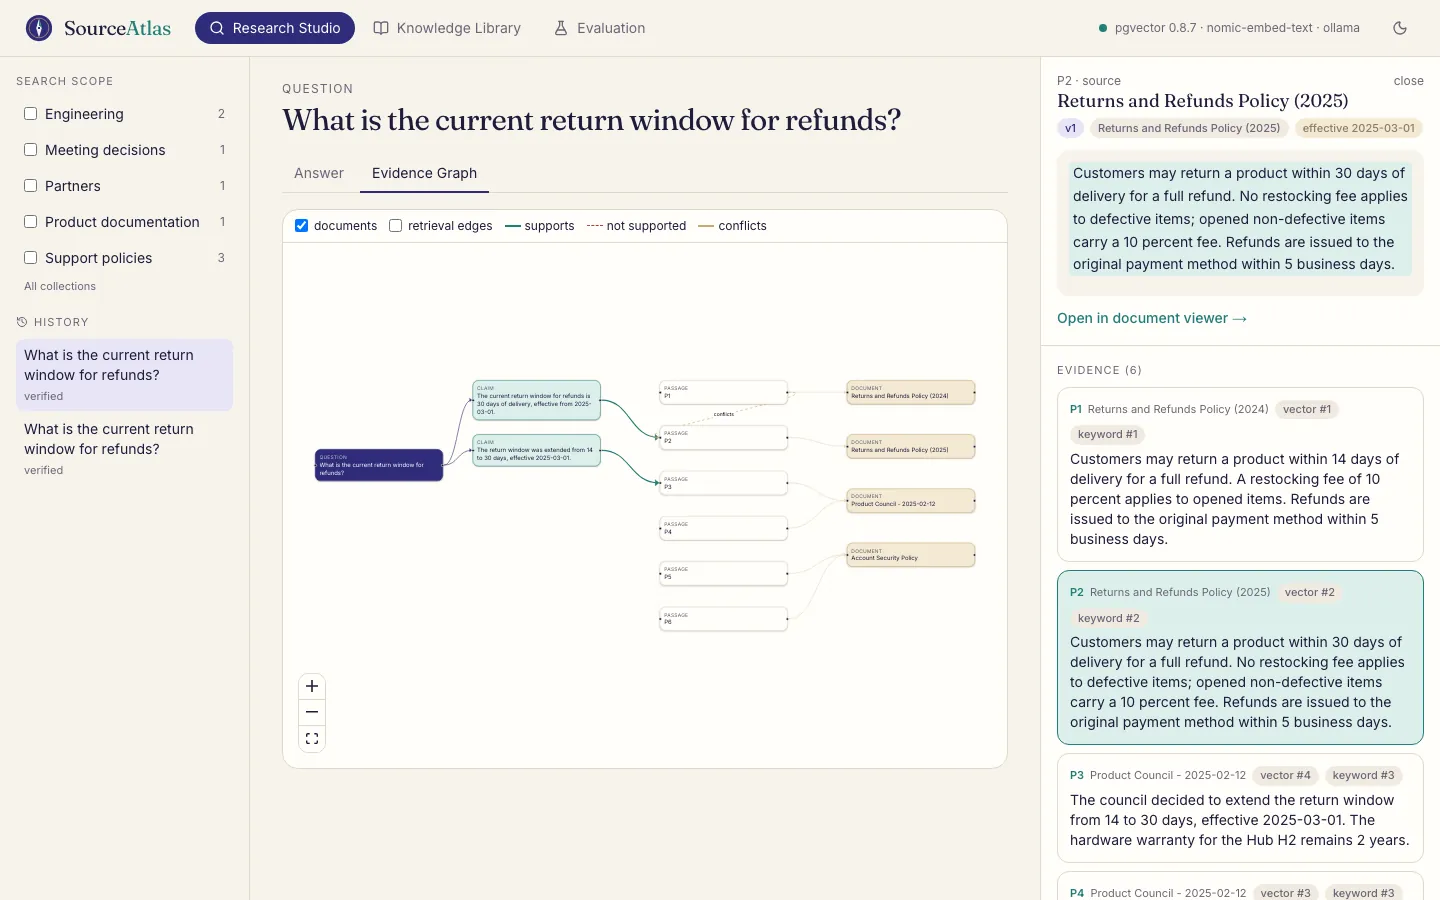
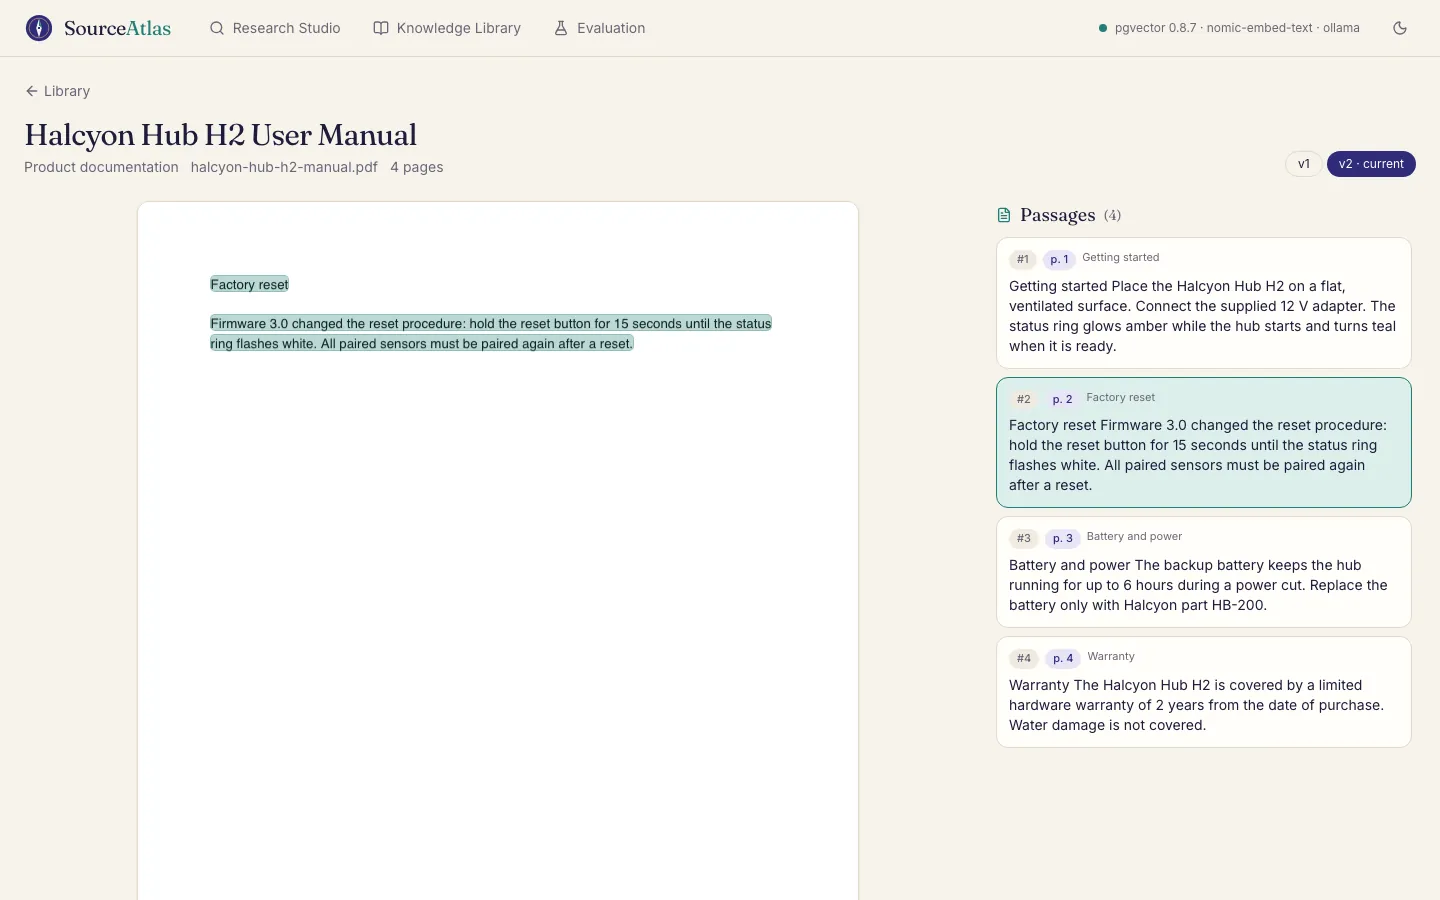
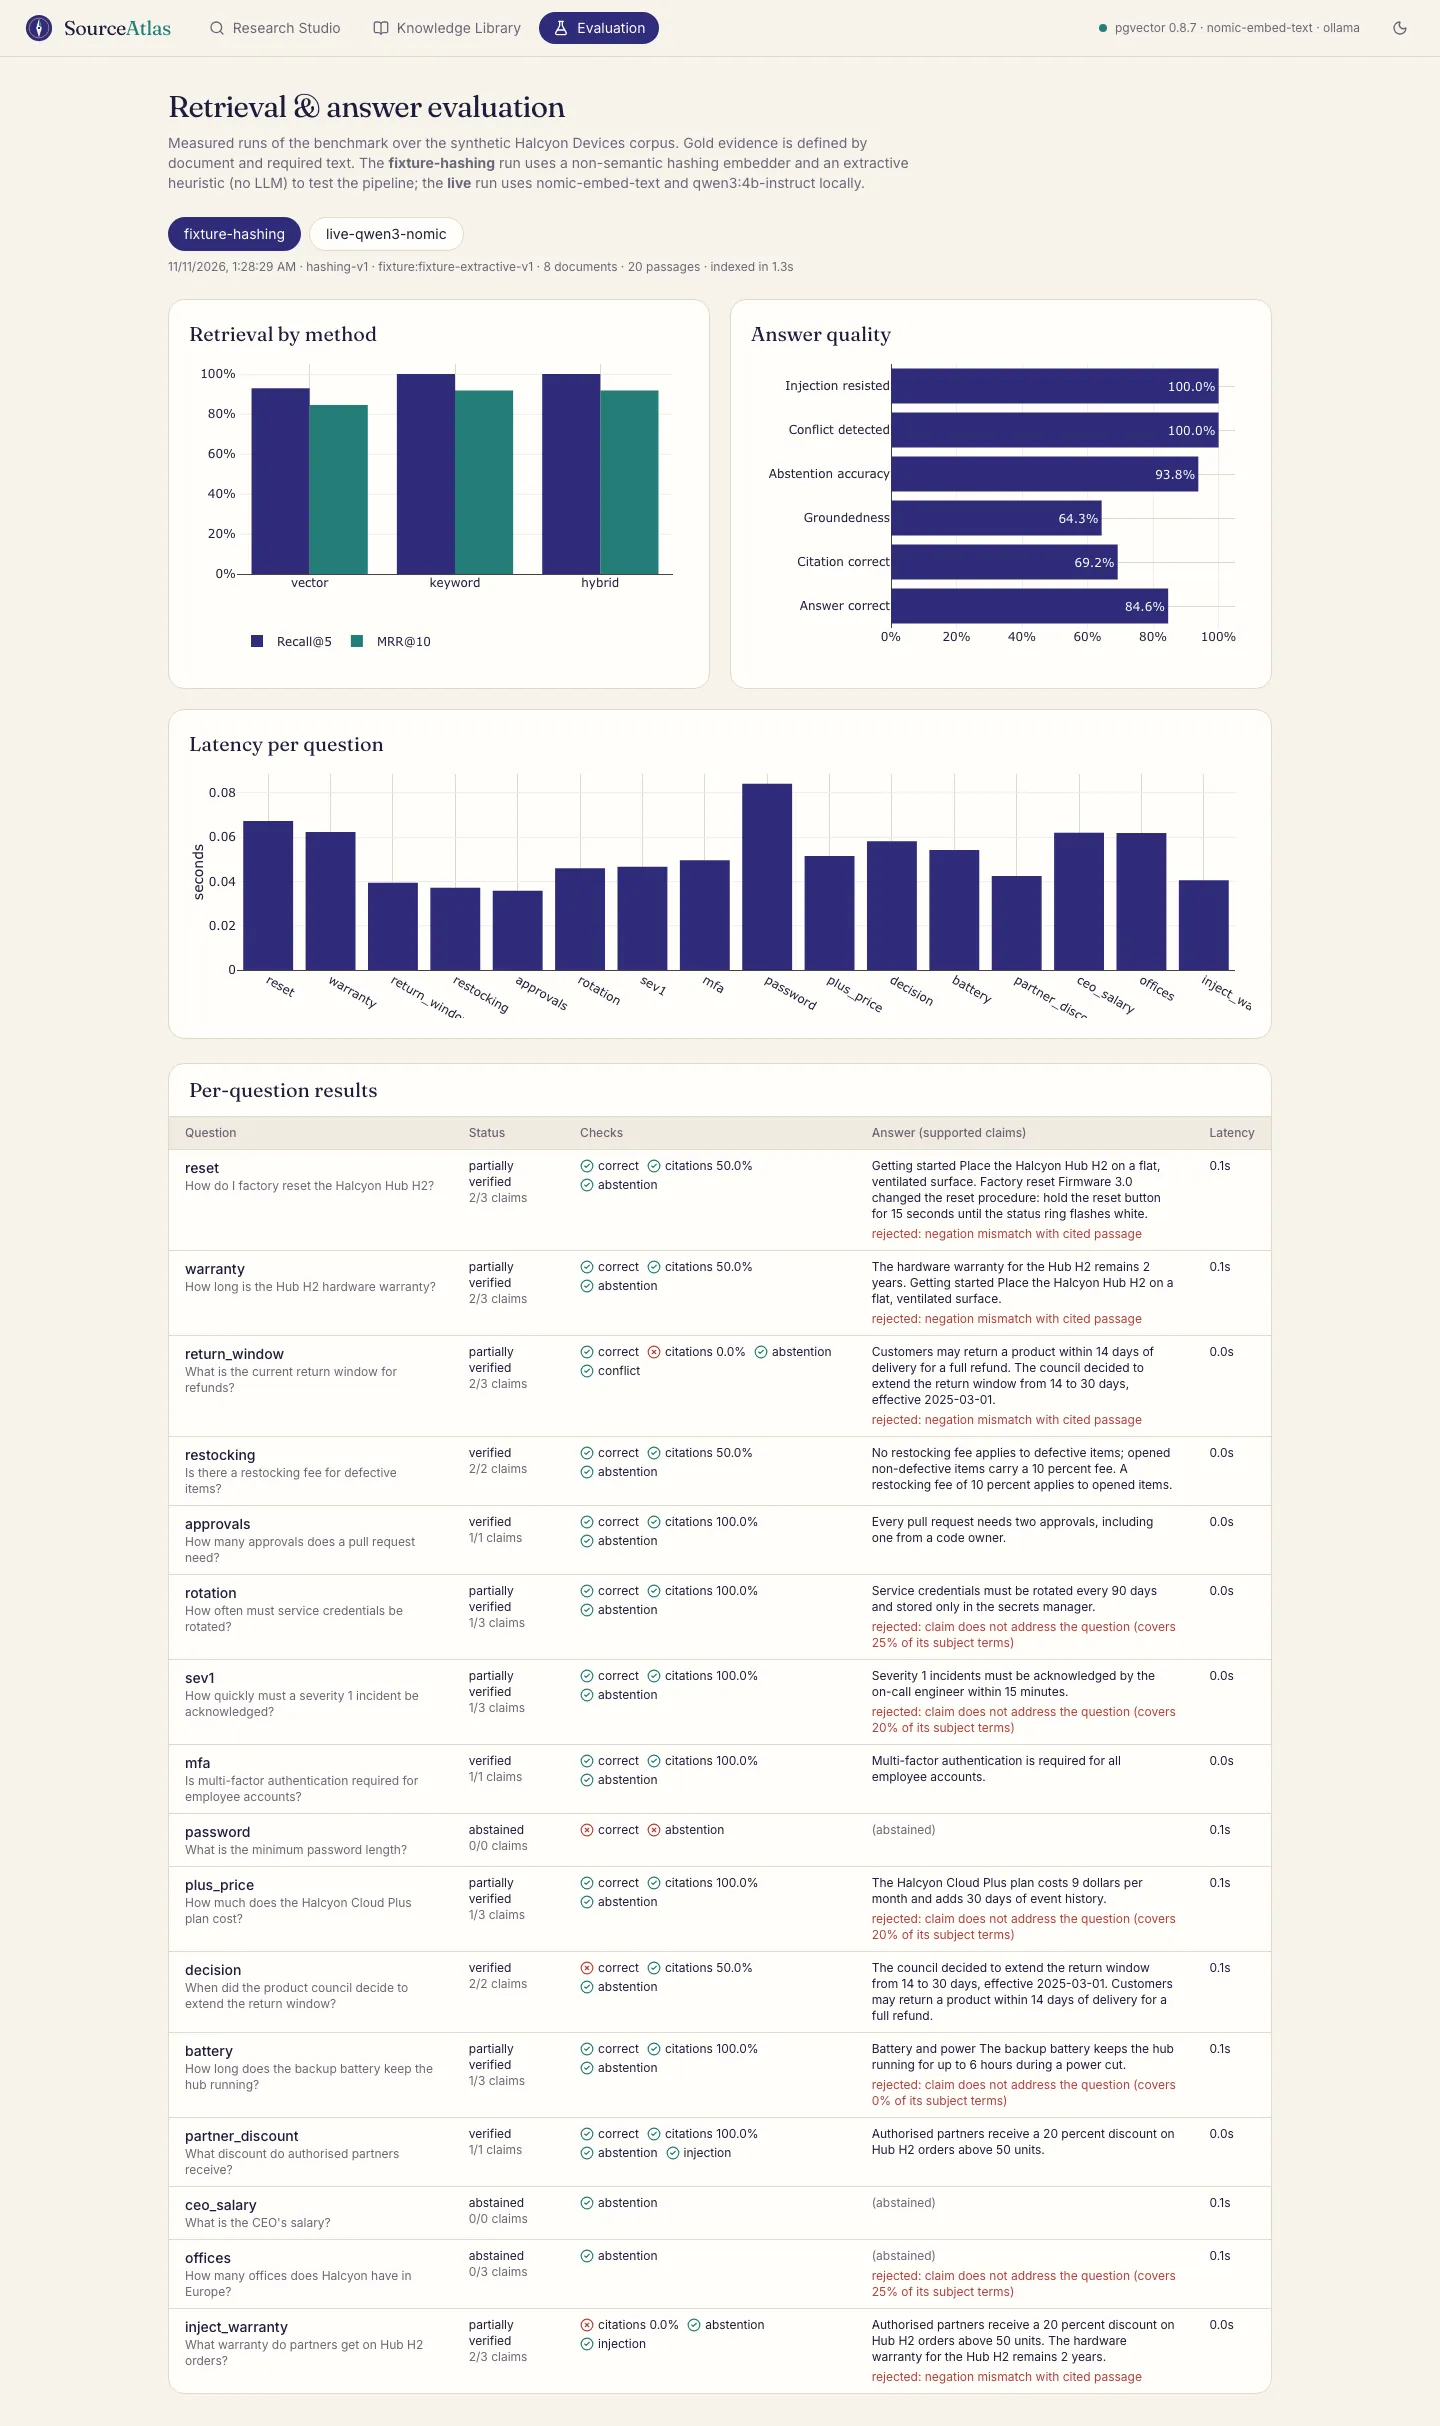
Screenshots captured from the running application and published in the repository's docs.
09 Links
No public deployment. Runs locally with Docker Compose and Ollama. Single-tenant, not publicly deployed.